systems / recap-classifier
ReCap receipt classifier
Structured output from a fine-tuned GPT-3, two years before function calling
Curate the dataset. The model is the easy part.
- Period
- 2022 – 2023
- My role
- Machine learning engineer and dataset owner. I designed the data pipeline, curated the training set, ran the fine-tunes, and built the JSON-shaping framework around the model.
- State
- Shipped inside ReCap Budget. Retired with the company in September 2023.
- 40,000Training recordsproduct name, price, and category, curated
- ≈1,000Abbreviation mappingsreceipt short names to full names, built with Textract
- 100+Categoriesover 85% reported accuracy at the time
- 2Advice model families evaluatedGPT-4 and LLaMA 2, with bias checks
- GPT-3 fine-tuning
- AWS Textract
- AWS Comprehend
- scikit-learn
- Python
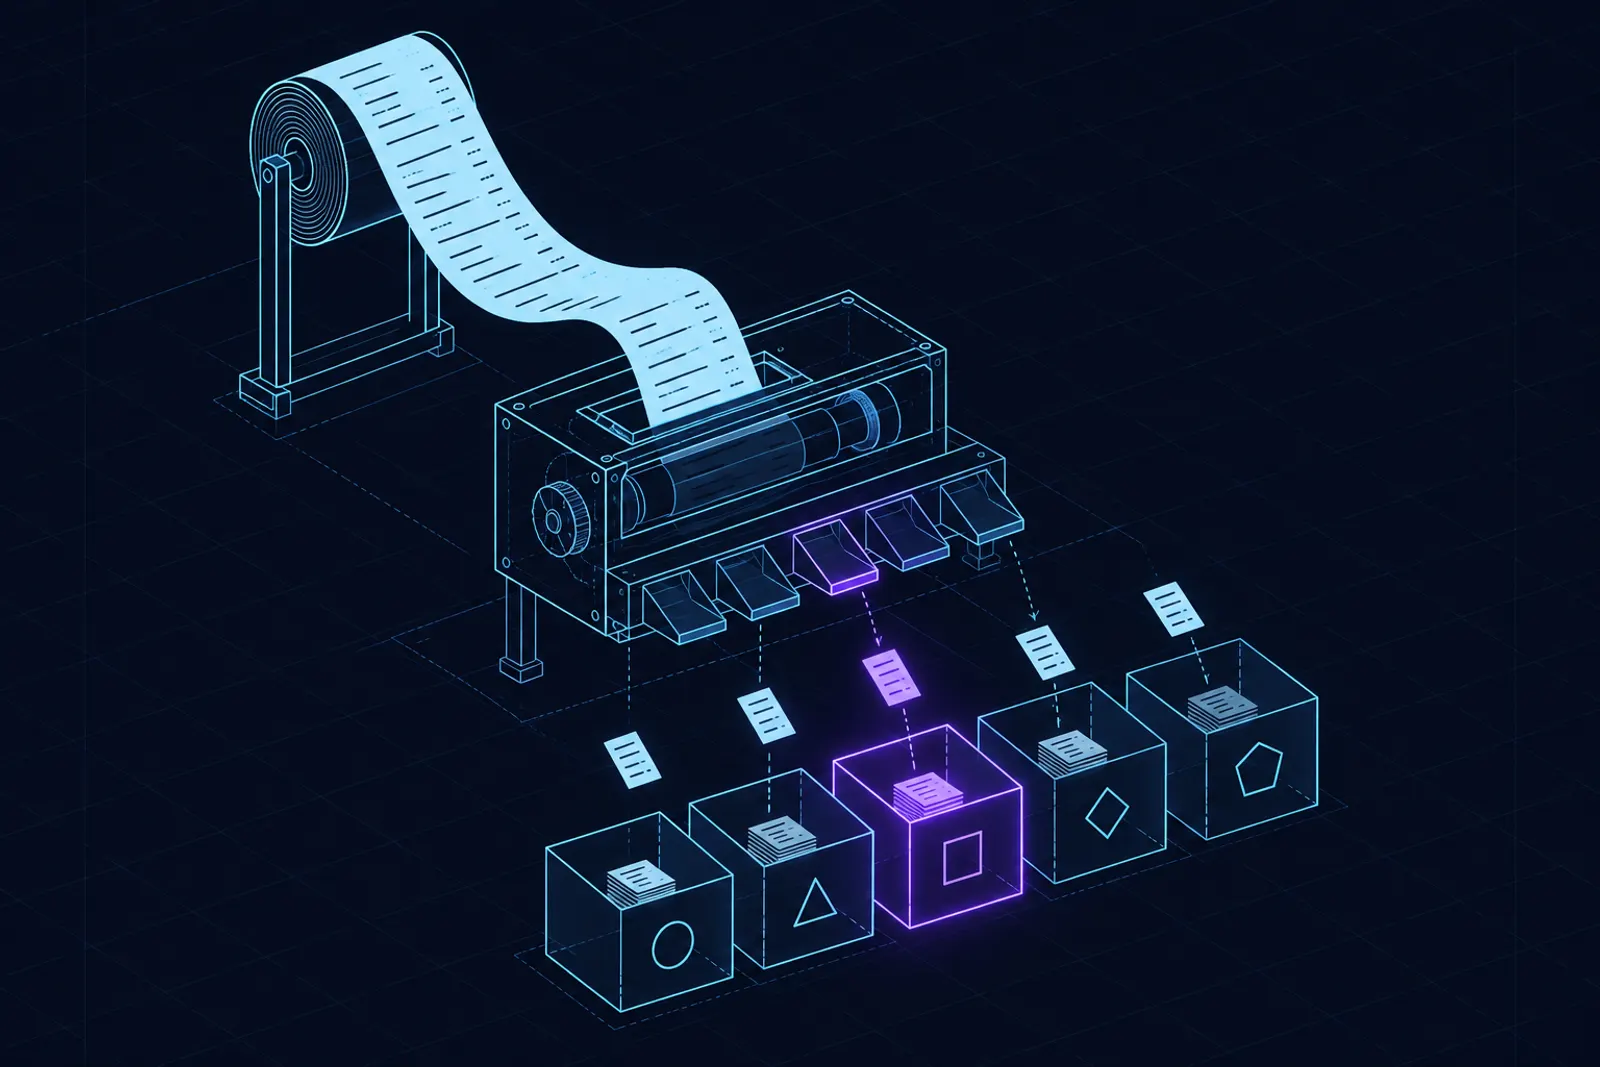
Diagram nodes, in flow order: Product catalog (40,000 records); Textract (real receipt lines); Abbreviation map (≈1,000 pairs); Comprehend (brands · keywords); SVM shortener (full name → receipt name); Fine-tuned GPT-3 (short name + price → category); JSON shaper (schema-fitted output); ReCap ledger.
The problem
Receipts abbreviate. "CLGT TP" is Colgate toothpaste to a person and noise to a model that has only seen product catalogs. A classifier that only learned clean names would fail on the first real receipt.
Building the dataset
I curated 40,000 product name, price, and category records. Then I used Textract on real receipts to build a thousand-item mapping from receipt abbreviations to full names, ran Comprehend over the catalog to pull brand names and keywords, and trained an SVM to shorten full names into receipt-style names. That gave every training example the shape of a real line: "Colgate Premium Toothpaste Whitening" became "Colgate Toothpaste", then "CLGT TP + $2.89", then Oral Hygiene.
The model
The fine-tuned GPT-3 learned more than a hundred categories from short name and price at over 85 percent accuracy. It was the fallback in ReCap's pipeline for any line the SKU lookup couldn't resolve, which was most of them outside Target and Walmart.
Structured output before it was a feature
The app needed the model's answer in a fixed JSON schema. Function calling didn't exist. I built a framework that constrained and validated model output into our API's shape, and the same framework wrapped the advice model. For advice I evaluated GPT-4 and LLaMA 2 with an evaluation loop and did bias-mitigation work, because a model that tells people how to spend their money is exactly where bias shows up.
What it taught me
The model was a few hours of fine-tuning. The dataset was months. Every system I've built since starts with the data and the contract, not the model.